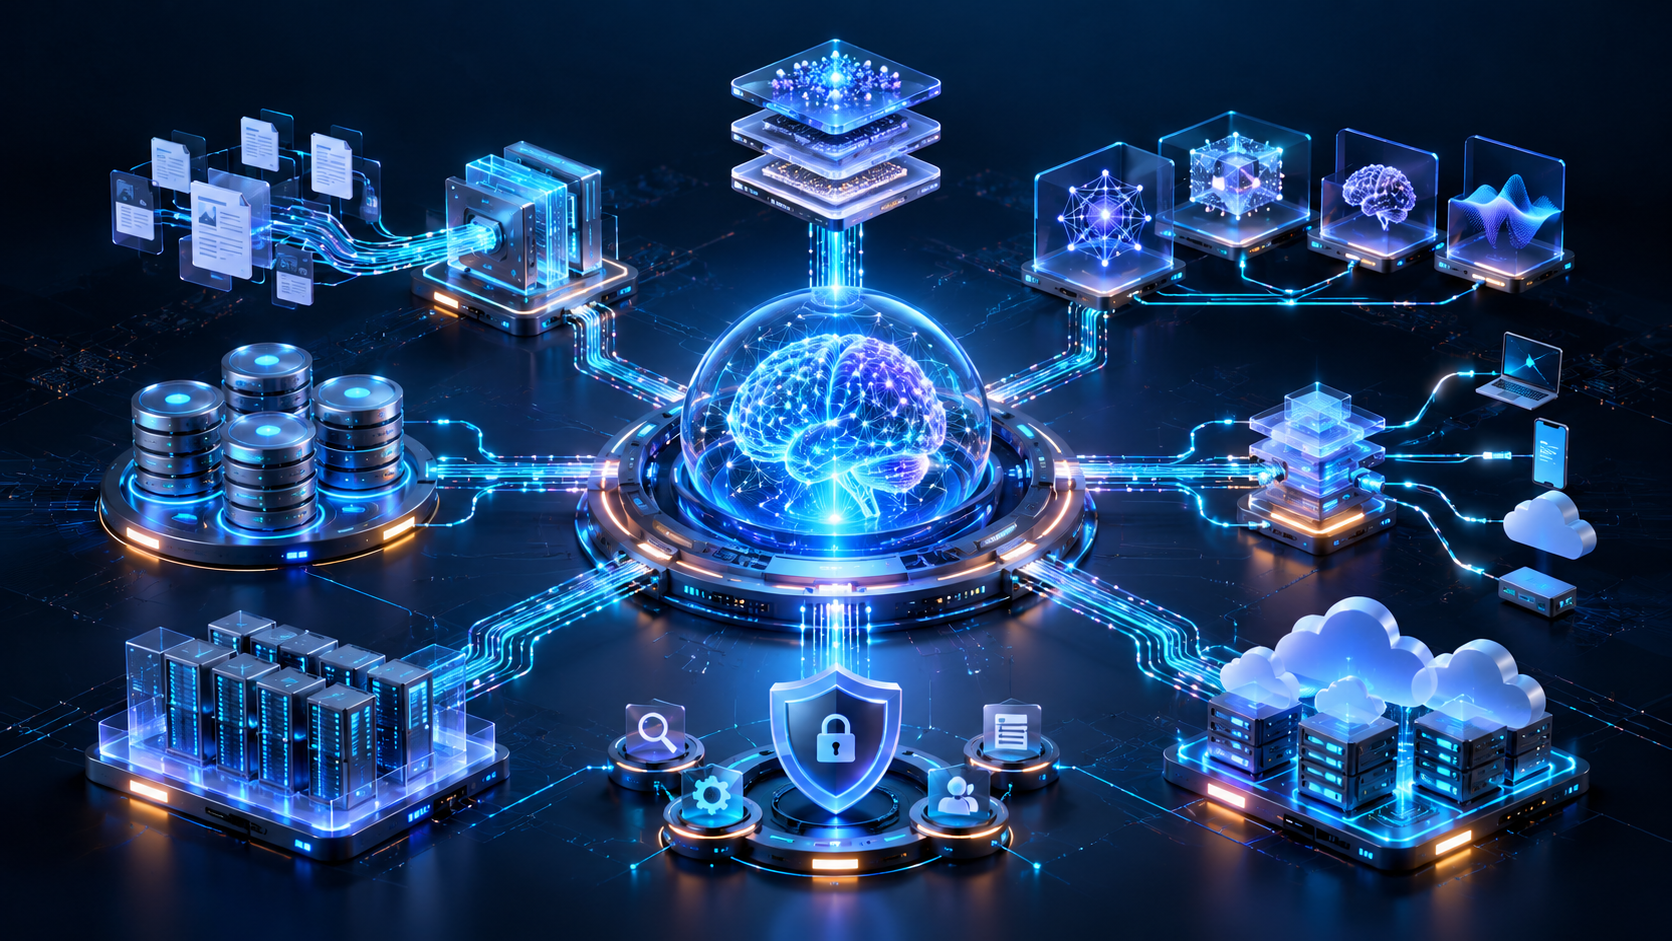
Generative AI application architecture defines how AI models, enterprise data, APIs, and security controls work together to deliver reliable AI-powered business applications. The right architecture helps organizations integrate AI into existing workflows while managing response quality, data privacy, scalability, and operating costs.
Choosing a model is only one part of the process. Businesses investing in generative AI development services must also determine when to use retrieval-augmented generation (RAG), how to connect AI with enterprise systems, and which governance controls are necessary for production deployment.
This guide explains the core layers of generative AI architecture, compares common implementation approaches, and outlines the decisions business leaders should make before scaling an AI application.
What Is Generative AI Application Architecture?
Generative AI application architecture is the design of the components that enable an AI application to process requests, retrieve relevant information, generate responses, and interact with business systems securely. It connects models, application services, data infrastructure, APIs, and operational controls into a coordinated system.
Unlike traditional applications that primarily follow predefined business logic, generative AI applications produce outputs influenced by model capabilities, prompts, and available context. Their architecture must account for variable responses, potential inaccuracies, data quality, and inference costs.
The appropriate design depends on the use case, data sensitivity, integration requirements, and expected workload. Understanding these factors helps businesses avoid unnecessary complexity while preparing production applications.
What Are the Core Layers of Generative AI Architecture?
A generative AI application typically contains five interconnected layers. Each has a distinct responsibility, but all must work together to deliver reliable results.
1. Application and API Layer
This layer receives user requests and connects the application with backend services. It handles authentication, request validation, session management, and communication with external systems.
An API gateway can enforce rate limits, authenticate clients, and centralize access policies. These controls help protect backend services and prevent unauthorized requests.
2. Orchestration and Prompt Management
The orchestration layer coordinates the steps required to answer a request. It determines whether to retrieve information, invoke a model, call an external tool, or apply additional validation.
Prompt management defines how instructions and contextual information reach the model. Prompt versioning and testing help teams identify regressions before deployment.
3. Model and Inference Layer
This layer contains the foundation model responsible for generating text, summaries, or other outputs. Applications can use hosted model APIs or models deployed within their own infrastructure.
Model selection affects response quality, latency, scalability, data handling, and operating costs. Model routing can direct requests to different models according to task complexity and performance requirements.
4. Data and Retrieval Layer
The data layer provides access to information required by the application. It may include relational databases, document repositories, enterprise search systems, and vector databases.
Retrieval systems help applications access relevant information without including entire datasets in every model request.
5. Security and Observability Layer
Security and observability controls operate across the architecture. They support access management, sensitive-data protection, audit logging, response evaluation, and performance monitoring.
Architecture flow: User request – API gateway – orchestration layer – authorized data retrieval, when needed – model inference – response validation – user response.
How Do You Choose the Right AI Model and Deployment Approach?
Model selection should begin with the business problem rather than a vendor’s feature list. Organizations should evaluate accuracy, reasoning requirements, latency, data sensitivity, expected usage, and total operating costs.
Hosted model APIs simplify implementation because providers manage much of the underlying infrastructure. They can help organizations launch applications quickly, but provider pricing, service limits, availability, and data-handling policies require evaluation.
Self-hosted models offer greater control over deployment environments and data-handling arrangements. However, businesses must account for infrastructure expenses, capacity planning, model updates, and operational expertise.
The main implementation approaches serve different purposes:
| Approach | Best suited for | Main consideration |
| Direct model API | Summarization, content generation, and general conversational tasks | Private or current information requires additional context or integration |
| RAG | Enterprise knowledge and frequently changing information | Retrieval quality, indexing, and permissions need ongoing management |
| Fine-tuning | Specialized task behavior and consistent output patterns | Requires suitable training data and systematic evaluation |
| Tool-enabled workflows | Applications that retrieve live data or perform business actions | Tool permissions and action validation are essential |
These approaches can work together. An enterprise assistant, for example, can use RAG to retrieve approved documents, a model API to generate answers, and controlled tool integrations to retrieve live business information.
Fine-tuning is generally more appropriate for adapting model behavior than for supplying frequently changing facts. Businesses should select each component according to a clearly defined requirement.
How Does RAG Fit into Generative AI Architecture?
Retrieval-augmented generation connects a language model with external or enterprise information. It helps applications produce responses grounded in relevant data that may not be available in the model’s original training.
A typical RAG architecture contains two workflows: preparing information for retrieval and processing user requests.
1. Prepare and Index Enterprise Data
The ingestion process collects information from approved sources, such as company documents, knowledge bases, product catalogs, and internal databases. Documents are cleaned, divided into manageable chunks, and converted into numerical representations called embeddings.
The system stores these representations alongside the associated content and metadata. A vector database supports semantic similarity searches, while keyword retrieval or hybrid search can improve results for exact terms and specialized terminology.
Document parsing, chunk size, metadata quality, and indexing strategies all influence retrieval performance.
2. Retrieve Relevant Context
When a user submits a question, the application converts it into a retrieval query. The retrieval system identifies relevant passages and may rerank them according to their relevance.
For an enterprise knowledge assistant, the system must verify the employee’s permissions before returning documents. Retrieval should never bypass the access restrictions of the original data source.
3. Generate a Grounded Response
The application supplies selected passages and the user’s question to the model. The model generates a response using the retrieved context and applicable instructions.
Source attribution, output validation, and fallback responses can improve transparency. However, RAG does not eliminate hallucinations. Incorrect retrieval, incomplete source material, or unsupported model inferences can still produce unreliable answers.
RAG is especially useful when information changes frequently or comes from private organizational sources. Fine-tuning addresses different needs, such as adapting task behavior or output consistency. The right choice depends on whether the primary requirement concerns access to knowledge or changes in model behavior.
How Do APIs and Orchestration Work in Generative AI Applications?
APIs connect generative AI applications with models, retrieval services, databases, and existing business systems. A well-designed API structure helps organizations manage these integrations without tightly coupling every component.
The application backend should control model access rather than expose provider credentials directly to client applications. Centralized interfaces also make it easier to change model providers, introduce retrieval services, and enforce consistent security policies.
Several controls are essential:
- Authentication and authorization: Verify identities and restrict access to approved resources and actions.
- Rate limiting: Prevent excessive requests from overwhelming services or increasing costs unexpectedly.
- Timeouts and retries: Handle temporary failures without creating uncontrolled request loops.
- Fallback mechanisms: Provide alternative models, cached information, or clear error messages when dependencies fail.
- Version management: Track API and prompt changes to reduce compatibility problems.
Applications that invoke external tools or business systems need additional safeguards. A model should not execute sensitive actions simply because a prompt requests them. The application must validate permissions, arguments, and business rules before executing each operation.
These controls help businesses maintain predictable behavior as AI integrations expand across their operations.
How Do You Build Governance and Security into AI Architecture?
AI governance should be incorporated throughout the application lifecycle. A well-defined AI product architecture helps enforce security controls, manage data access, and monitor model behavior. Policies alone cannot protect an application if its architecture permits unauthorized data access, unsafe tool execution, or unmonitored model behavior.
Protect Data and Control Access
Organizations should classify sensitive information, encrypt data in transit and at rest, and apply access controls to databases, retrieval systems, and model interfaces. Data retention policies should define how prompts, responses, and logs are stored and when they are deleted.
For RAG applications, permissions must apply at the document or record level. Retrieved content should not bypass existing enterprise access rules. Teams should also assess whether sending particular data to an external model provider complies with their privacy and contractual requirements.
Defend Against AI-Specific Risks
Prompt injection can manipulate a model into ignoring instructions or attempting unauthorized actions. Indirect prompt injection can also originate from retrieved documents or external content.
Useful safeguards include input screening, output validation, tool allowlists, least-privilege permissions, and human approval for high-impact actions. Sensitive information should be protected through appropriate redaction and data-handling controls. These measures complement conventional application security; they do not replace it.
Establish Accountability and Oversight
Governance requires documented ownership, audit trails, risk assessments, and escalation procedures. Organizations should determine who approves model changes, investigates incidents, and reviews application performance.
The NIST AI Risk Management Framework provides a useful reference for identifying, assessing, and managing AI-related risks. Businesses should adapt governance controls to their regulatory obligations, industry, and application risk level.
How Do You Evaluate and Scale a Generative AI Application?
Production readiness requires evidence that an application performs reliably under realistic conditions. A successful demonstration does not establish that a system can handle changing data, concurrent requests, unexpected inputs, or service failures.
Start by creating an evaluation dataset that represents common requests, difficult questions, edge cases, and potentially harmful inputs. Measure factual accuracy, groundedness, task completion, and policy compliance against defined acceptance criteria.
Operational monitoring should track response latency, API errors, token consumption, retrieval failures, and cost per completed task. The 95th-percentile latency (p95) helps teams understand slower user experiences that averages can conceal.
Caching can reduce repeated computation, while model routing and batching may improve efficiency for suitable workloads. Scaling policies should account for traffic spikes, provider quotas, context-window limits, and retrieval bottlenecks. Continuous evaluation, controlled releases, and incident-response procedures help maintain quality as models, prompts, and business requirements evolve.
Conclusion
Generative AI application architecture requires more than selecting a model. Businesses must align model capabilities, data retrieval, API integrations, security controls, and evaluation processes with their operational requirements.
Before scaling an AI application, define success metrics, establish data-access and governance requirements, and validate the architecture against realistic workloads. Resources such as AppDevGuides can help businesses explore app development concepts and make more informed technical decisions. Start with the components the use case requires, measure their performance, and introduce additional complexity only when the evidence supports it.
Frequently Asked Questions
1. What is generative AI application architecture?
Generative AI application architecture defines how models, application services, data sources, APIs, and security controls work together to process requests and generate responses. It provides the foundation for reliable, scalable AI applications.
2. What are the main components of a generative AI application?
The main components include the user interface, backend services, API gateway, orchestration layer, AI model, data and retrieval systems, security controls, and monitoring services. Their configuration depends on the application’s requirements.
3. Why is RAG important in generative AI architecture?
RAG retrieves relevant information from external or enterprise data sources and provides it as context to a language model. This helps applications generate domain-specific responses without retraining the model for every data update.
4. What is the difference between RAG and fine-tuning?
RAG provides relevant information at inference time, making it useful for current or private knowledge. Fine-tuning changes model weights using training examples to adapt behavior, task performance, or output consistency.
5. How do you secure a generative AI application?
Secure generative AI applications with strong access controls, data encryption, permission-aware retrieval, input and output validation, tool restrictions, audit logging, and continuous testing. High-impact actions should include appropriate human oversight.
